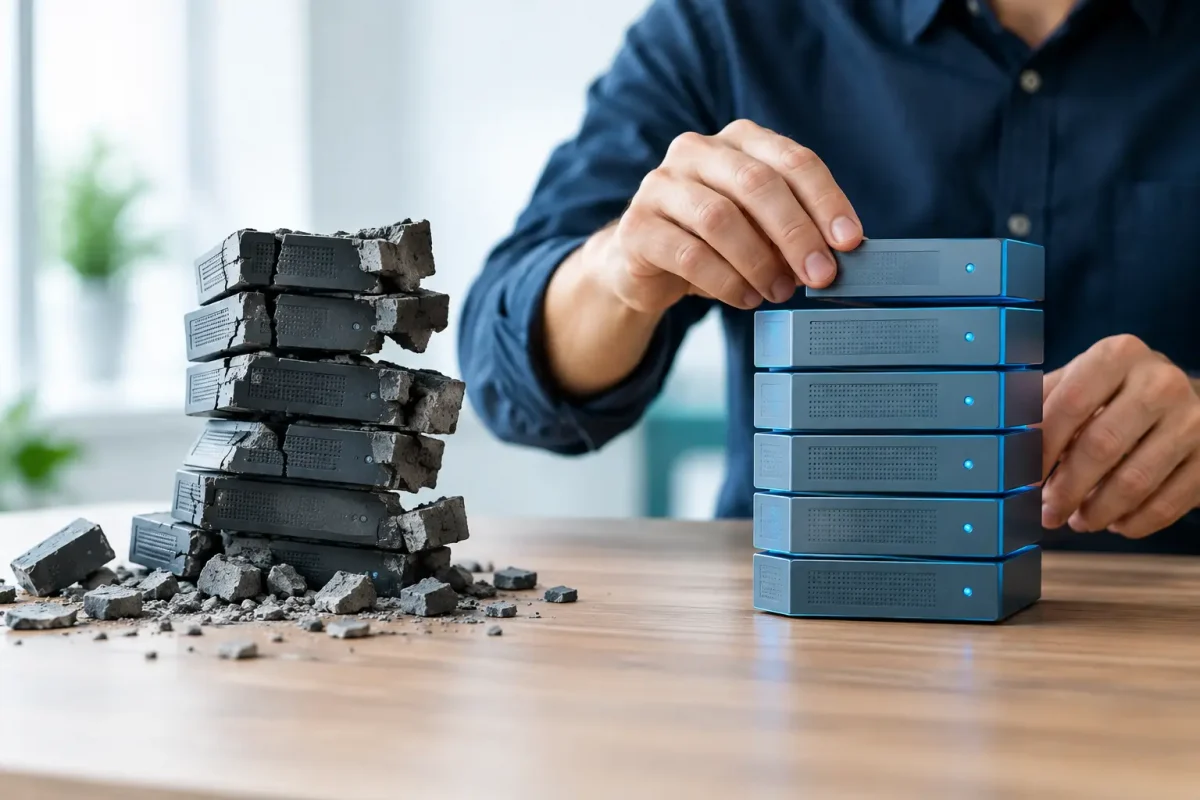
A failed application is rarely just a technical problem. By the time leadership considers replacing it, the damage usually includes delayed revenue, workarounds that distort operations, frustrated customers, staff who no longer trust the system, and a project team reluctant to make another promise.
Rebuilding failed enterprise applications is therefore not a matter of assigning a new development team and restarting the backlog. That approach often recreates the conditions that caused the first failure: unclear ownership, untested assumptions, hidden integration complexity, and decisions made without a reliable view of the business operation the software must support.
The first responsibility is to determine whether the application actually failed, or whether the delivery model around it did.
Start with a failure diagnosis, not a rewrite plan
Many executives inherit a familiar recommendation: the existing system is messy, so replace it. Sometimes that is correct. But a full rewrite is also the most expensive way to avoid understanding the current problem.
An enterprise application can appear beyond repair because it is slow, difficult to change, insecure, poorly documented, or dependent on a vendor that has lost credibility. Those are serious conditions, but they have different remedies. A system with weak code quality may still contain valuable business rules developed over years. A stalled project may have acceptable technology but no agreed product decisions. A portal with recurring defects may be suffering from unreliable upstream data rather than flaws in the portal itself.
Before selecting an architecture or estimating a rebuild, leadership needs clear answers to a few diagnostic questions:
- Which workflows create the most financial, operational, or customer risk when the system fails?
- What data, integrations, permissions, and compliance obligations are hidden behind the visible interface?
- Which behaviors are essential, and which were added through years of exceptions and workarounds?
- Can the current application remain safely in service while replacement components are introduced?
This work is not a prolonged academic exercise. It is a disciplined way to reduce expensive uncertainty early. Without it, a new team can produce cleaner code while preserving bad process design and missing the dependencies that make the old system hard to replace.
Stabilize the business before rebuilding the application
A broken application often forces organizations into emergency behavior. Teams use spreadsheets to reconcile records, manually re-enter transactions, or rely on one employee who knows how to get the system through month-end. Those workarounds may keep the business moving, but they also conceal the real cost of the failure.
The immediate objective is not elegance. It is operational control.
That may mean addressing a small number of defects that block orders, claims, fulfillment, reporting, or customer service. It may mean adding monitoring around fragile integrations, documenting manual fallback procedures, or isolating a risky module so it does not compromise the rest of the platform. In some cases, preserving the existing application for a defined period is safer than trying to replace every function at once.
This is where conventional advice to move fast can become dangerous. Speed matters, but unstructured speed produces a second rescue project. A capable technical partner should help leadership separate urgent stabilization work from strategic modernization work, with different decision rights and success criteria for each.
Protect the source of truth
Data migration is often treated as a late-stage implementation task. In failed enterprise builds, it deserves early executive attention.
If customer records, pricing logic, operational histories, documents, or financial status are inconsistent, a new interface will not fix the underlying problem. The rebuild needs a deliberate answer to where each critical piece of data originates, who can change it, how conflicts are resolved, and what must be retained for legal or operational reasons.
A useful rebuild can temporarily operate alongside older systems. An uncontrolled rebuild creates multiple competing versions of reality.
Decide whether to rebuild, replace, or modernize in stages
There is no universal case for a complete rewrite. The right path depends on the condition of the application, the urgency of the business need, and the cost of maintaining parallel operations.
A full rebuild is appropriate when the existing architecture cannot meet security, performance, scalability, or maintainability requirements and the application’s core purpose remains strategically important. It can also make sense when accumulated fixes have made change predictably expensive and risky.
Incremental modernization is often stronger when the current system still supports critical operations, but individual components create friction. A company may replace a customer-facing portal while retaining a back-office system temporarily. It may modernize integration layers first, making future changes less dependent on brittle point-to-point connections. Or it may build a new workflow around the highest-value operational bottleneck, then retire older modules as adoption grows.
Replacement with a commercial platform is another valid option when the business process is relatively standard. The caution is that buying software does not eliminate design work. It changes the work. Leadership must still decide where to standardize, where customization is genuinely justified, how the platform fits existing systems, and who owns the resulting operating model.
The mistake is treating these choices as technology preferences. They are investment decisions. A full rebuild concentrates risk and can create a cleaner long-term foundation. Staged modernization lowers immediate disruption but requires disciplined integration and transition planning. Commercial software may reduce custom build effort but can introduce vendor constraints and process compromises.
Rebuild around outcomes, not feature parity
Feature parity is one of the most common traps in application rescue. Teams inventory every screen and request, then set out to duplicate the old system. That feels safe because it is concrete. It is also how organizations spend significant money preserving obsolete behavior.
A better question is: what business outcome was each feature intended to produce, and does that outcome still matter?
For example, a complex approval sequence may exist because the old system could not provide visibility, not because five people need to approve every exception. A report may be widely used because managers cannot access timely operational data elsewhere. A manual export may exist only because two systems were never properly integrated.
This does not mean dismissing user knowledge. Frontline teams often understand failure points better than project sponsors do. It means converting requests into decisions about revenue, capacity, control, customer experience, and risk. The rebuild should preserve the business capabilities that matter, not the historical shape of a troubled application.
Make the operating model visible
Enterprise software fails when ownership is vague as often as it fails when code is weak. Someone needs authority to make product decisions, define acceptable trade-offs, and resolve conflicts between departments. Someone else needs accountability for technical quality, security, integration decisions, and the ability to maintain the system after launch.
Those roles may be held internally, externally, or jointly. What matters is that they are explicit. A steering committee that meets monthly cannot substitute for timely decisions on data ownership, workflow design, and scope changes.
For each major release, leadership should be able to see what business process is changing, what assumptions are being tested, what systems are affected, and what would happen if the release is delayed or rolled back. That level of visibility is not bureaucracy. It is how executives retain control over a consequential investment.
Build for the transition, not just the launch
The launch date is not the finish line for a rescued application. The real test is whether the organization can operate, support, improve, and govern the system without returning to dependency on a single vendor or a handful of employees.
That requires practical engineering discipline: documented architecture decisions, test coverage proportional to business risk, deployment processes that do not depend on heroics, observability for key workflows, and clear ownership of integrations. It also requires adoption planning. If a new system changes how sales, operations, finance, or service teams work, the project must account for training, permissions, reporting, and exceptions.
A technically sound launch can still fail commercially if teams revert to familiar workarounds. Conversely, a phased rollout can create confidence when users see that feedback is acted on and operational continuity is protected.
One Blink Tech approaches these engagements as technical rescue and business systems work, not as a cosmetic replacement exercise. The goal is to establish a dependable foundation that gives leadership more visibility and control while making future change less costly.
The strongest rebuild is not the one that looks newest on launch day. It is the one that leaves the business less dependent on workarounds, less exposed to operational surprises, and more capable of changing on purpose.